
We provide NLP Services for Text Analysis & Language AI

Seller
Rudrriv Technologies
★★★★★4.9 (3,657 reviews)
✓Share the text data, target task and expected output. We provide the agreed NLP pipeline, evaluation, quality review, code and final handoff.
✦Service Highlights
  • NLP delivery for structured text-analysis and language-processing use cases.
  • Scopes can cover classification, sentiment, entity extraction, topic analysis, semantic matching, summarization and custom text pipelines.
  • Model choice is based on your data, language, quality target, latency needs and integration context—not a one-model-fits-all approach.
  • Packages include reproducible code, evaluation evidence and documented assumptions according to the selected scope.
  • You purchase a defined NLP service with clear scope, deliverables, evaluation and handoff.

What Clients Appreciate in Related AI Delivery

The supplied testimonial below relates to a Deep Learning engagement and is shown with its original service label rather than being relabelled as NLP.

H
Henry Cooper🇦🇺 Australia5 / 5
Deep Learning
What stood out in the Deep Learning work was the combination of careful analysis, practical implementation, and clear communication. We appreciated the rigor around GPU efficiency, validation strategy, reproducibility, network architecture, and training stability, along with the way assumptions and limitations were documented as the project evolved. By the end, we had higher-quality predictions on difficult cases without sacrificing a disciplined evaluation process. We also received reproducible training notebooks, checkpoints, metrics, and tuning documentation, which made internal adoption straightforward.
3 weeks ago

About This Natural Language Processing Service

Turn unstructured text into a usable model, pipeline or decision signal

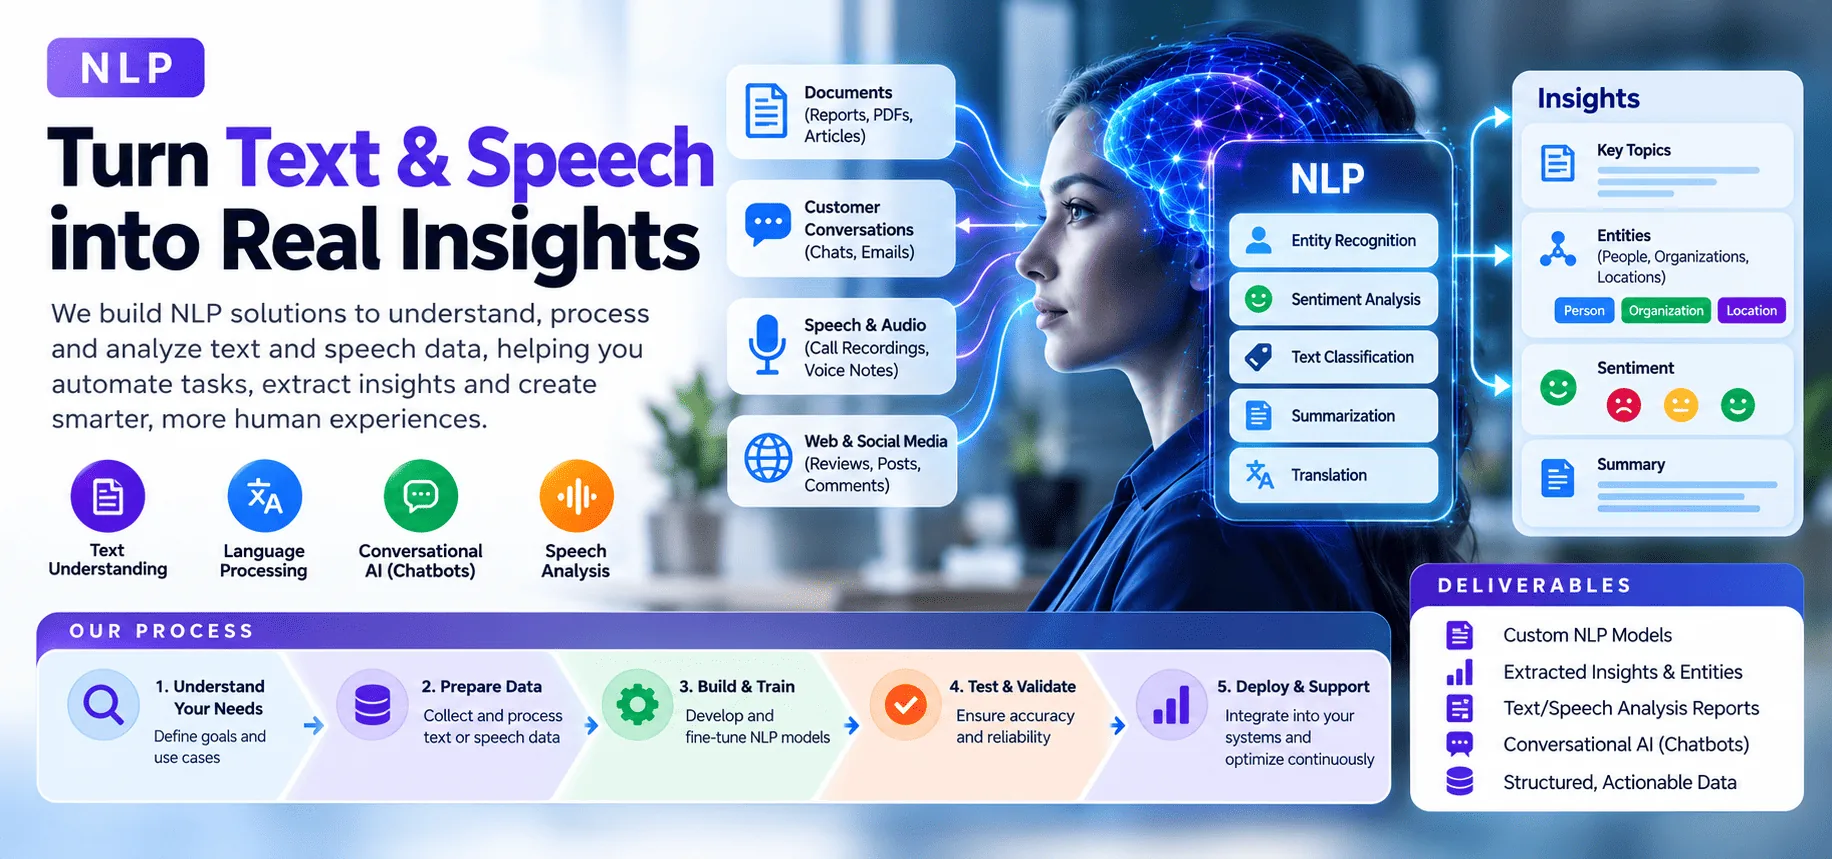
Natural language processing (NLP) applies computational methods to understand, classify, extract, compare or generate information from human language. Businesses use NLP when text is too large, repetitive or unstructured for reliable manual handling—for example support tickets, customer feedback, documents, product reviews, survey responses, knowledge bases and internal records.

Rudrriv provides the complete NLP service around the agreed scope. We assess the business objective and data, implement the selected approach, review the evidence behind model decisions and deliver the code, artifacts and documentation included in your package.

What this service can include
  • Text classification: categorize messages, documents, tickets or feedback into a business-defined taxonomy.
  • Sentiment analysis: identify positive, negative, neutral or task-specific opinion signals with confidence-aware evaluation.
  • Named entity recognition and information extraction: detect people, organizations, products, identifiers or domain-specific terms.
  • Topic and theme analysis: organize large text collections around recurring themes, issue clusters or content patterns.
  • Semantic similarity and matching: compare meaning rather than exact keywords for duplicate detection, retrieval or record matching.
  • Summarization and document processing: condense or structure longer content when the selected models and review process fit the use case.
  • Custom NLP pipelines: combine preprocessing, rules, embeddings, classical machine learning, transformer models or APIs where appropriate.
  • Evaluation and handoff: provide reproducible code, metrics, error analysis, model artifacts and technical documentation according to scope.
What we need from you

Share the business problem, a representative sample of the text, expected output, language or languages, any existing labels or taxonomy, approximate data volume, target environment, deadline and constraints around privacy or third-party services. If you already have a baseline, API, model, notebook or evaluation set, include it so the new scope can be assessed against the current state.

How the NLP delivery process works
01
Scope & data review

We clarify the target output, inspect representative text and confirm whether the available data supports the requested task.

02
Baseline & model selection

We select preprocessing and modelling options that fit the task, then establish a measurable baseline before deeper tuning.

03
Build, validate & review

The pipeline is implemented and evaluated with task-appropriate metrics, representative errors and documented assumptions.

04
Handoff & integration path

Approved code, model artifacts, metrics and documentation are packaged for internal use, integration or the next deployment stage.

Quality and technical considerations

Useful NLP work depends on more than selecting a model. We consider label quality, train/validation/test separation, leakage risk, class imbalance, domain language, multilingual coverage, latency, explainability and the cost of false positives or false negatives. Accuracy is not guaranteed in advance because performance depends on the data and task; the goal is to establish measurable evidence and make limitations visible.

Common tasks
Classification
Sentiment
Entity extraction
Semantic matching
Typical stack
Python
Hugging Face
spaCy / scikit-learn
Cloud NLP APIs where suitable
Handoff formats
Notebooks / source code
Model artifacts
Metrics & reports
Inference code / documentation

Compare NLP Service Packages

Choose the scope by data volume, level of customization, evaluation depth and whether you need reusable inference or API-ready handoff code.

Included
₹8,999
Essential
NLP Text Analysis Starter
For a focused proof of concept on one clearly defined language task.
₹24,999
Professional Recommended
Custom NLP Pipeline
For a reusable business pipeline with tuning, deeper validation and handoff code.
₹59,999
Advanced
NLP Model & API Build
For broader model work, advanced tuning and API-ready inference code.
Standard data volumeUp to 10,000 recordsUp to 50,000 recordsUp to 100,000 records
NLP task coverage1 focused task1 core taskUp to 2 linked tasks
Text preprocessing✓✓✓
Custom preprocessing pipeline—✓✓
Model selection / baseline✓✓✓
Model tuningBaseline only✓Advanced
Transformer fine-tuning—When suitableWhen suitable
Evaluation metrics✓✓✓
Detailed error analysisBasic✓✓
Reproducible notebook / source code✓✓✓
Model artifactIf applicable✓✓
Inference script—✓✓
API-ready endpoint code——✓
Revision rounds123
Standard delivery5 working days10 working days15 working days
Package price
₹8,999
₹24,999
₹59,999

Package limits assume reasonably accessible, machine-readable text. Larger datasets, data-labelling work, additional languages, third-party usage charges, production infrastructure and complex integrations can require a custom quote.

OUR WORK 05 NLP CONCEPT SAMPLES

NLP portfolio: from raw text to reviewable outputs

Explore five task-specific examples of the NLP deliverables we can scope: annotated text, model-evaluation workflows, ranking views and evidence-based review. All examples use synthetic, demonstrative data and are not past-client case studies or measured model results.

01 / 05Text classification

Intent Classification & Error Review

Route support tickets across a defined intent taxonomy, with auditable predictions, class-level errors and a worked confusion matrix.
Taxonomy designError reviewEvaluation matrix
02 / 05Named entity recognition

Contract Entity Extraction

Highlight organizations, dates, durations and monetary amounts, then map annotated spans to a reviewable structured output schema.

Span annotationEntity mappingSchema export
03 / 05Sentiment analysis

Aspect-Level Sentiment Mapping

Separate praise and complaints inside mixed feedback, assigning polarity to delivery, packaging and support phrases.

Aspect extractionMixed polarityAnnotation QA
04 / 05Semantic similarity

Semantic Knowledge Search

Rank help-centre passages by query meaning and examine the relevance decisions behind candidate search results.

Semantic rankingRelevance labelsRetrieval review
05 / 05Document summarization

Evidence-Linked Summarization

Turn longer project notes into source-attributed summaries, preserving conditions while flagging unsupported statements.

Source attributionSummary QAClaim screening

Frequently Asked Questions About NLP Services

Rudrriv’s NLP service can include requirements scoping, text-data review, preprocessing, model or pipeline selection, training or configuration, evaluation, error analysis, reproducible code, model artifacts and documentation according to the selected package, with quality review and final handoff.
Common scopes include text classification, sentiment analysis, named entity recognition, information extraction, topic or theme analysis, semantic similarity, document categorization, summarization and other text-processing pipelines. The exact approach is selected around your data, output requirements and deployment context.
Not always. Some tasks can begin with pre-trained models, zero-shot methods, rules or unsupervised techniques. Custom supervised models usually need labelled examples. If labels are missing, Rudrriv can assess whether a baseline, labelling plan or alternative approach is more appropriate.
Yes, when they fit the use case. A project may use transformer models, Hugging Face libraries, spaCy, scikit-learn, cloud NLP APIs or other suitable tools. The stack is chosen for accuracy, maintainability, latency, data constraints and the level of customization required.
Evaluation depends on the task. Classification projects may use precision, recall, F1 score and accuracy where appropriate; extraction tasks may use entity-level precision, recall and F1; ranking or similarity work may require task-specific measures. We also review representative errors instead of relying on a single headline metric.
Yes, but language support depends on the selected model, available training data and the task. Multilingual or non-English requirements should be shared at the start so language coverage, evaluation data and model suitability can be assessed before the scope is confirmed.
The Essential package starts at ₹8,999, the Professional package is ₹24,999, and the Advanced package is ₹59,999 for the standard scopes shown on this page. Larger datasets, additional languages, extra integrations, production infrastructure or unusual compliance requirements may need a custom quote.
Standard package delivery ranges from 5 working days for a focused proof of concept to 15 working days for the broader Advanced scope. Turnaround can change if data requires substantial cleaning, labels are incomplete, access is delayed or the project needs additional integrations.
Yes, the deliverables shown for each package include reproducible code. Model artifacts are included where a trained or fine-tuned model is part of the scope. Documentation explains how to run the delivered workflow and any dependencies or assumptions that matter for handoff.
The Advanced package includes API-ready inference endpoint code and deployment guidance. Production cloud deployment, authentication, monitoring, scaling, private-network configuration or complex application integration can be scoped separately when required.

Related AI Delivery Reviews

The supplied reviews are for Deep Learning engagements. They are preserved with their original customer names, countries, ratings, timelines, service labels and wording rather than being presented as NLP-specific testimonials.

J
Jasmine Koh
🇸🇬 Singapore
Deep Learning
4.9 / 5   •   1 month ago

We chose a specialist for Deep Learning because our requirements called for a deep-learning model for complex pattern recognition with measurable quality rather than a generic template. A lot of value came from the attention to reproducibility, network architecture, training stability, regularization, and GPU efficiency. Instead of hiding uncertainty, the team documented it and showed us where additional data or different assumptions would change the result. The final result gave us higher-quality predictions on difficult cases without sacrificing a disciplined evaluation process. We received reproducible training notebooks, checkpoints, metrics, and tuning documentation, and the transition into day-to-day use was smooth.

S
Samir Aziz
🇦🇪 United Arab Emirates
Deep Learning
4.8 / 5   •   6 weeks ago

Our priority in Deep Learning was reliability. The team designed a deep-learning model for complex pattern recognition with that requirement visible in every stage of the project. The team worked methodically through training stability, regularization, GPU efficiency, validation strategy, and reproducibility. That made revisions faster because issues were isolated, documented, and resolved rather than repeatedly resurfacing. Most importantly, we ended up with higher-quality predictions on difficult cases without sacrificing a disciplined evaluation process. The team packaged reproducible training notebooks, checkpoints, metrics, and tuning documentation in a way that made the next stage straightforward.

M
Mia Richter
🇩🇪 Germany
Deep Learning
5 / 5   •   2 months ago

The scope for Deep Learning looked straightforward at first, but the underlying data issues made it more complex. The team still kept the project focused around a deep-learning model for complex pattern recognition. The project stayed controlled because the team treated GPU efficiency, validation strategy, reproducibility, network architecture, and training stability as core requirements, not optional polish to be added at the end. The final result gave us higher-quality predictions on difficult cases without sacrificing a disciplined evaluation process. We received reproducible training notebooks, checkpoints, metrics, and tuning documentation, and the transition into day-to-day use was smooth.

S
Sophie de Vries
🇳🇱 Netherlands
Deep Learning
4.9 / 5   •   3 months ago

This was our first outsourced Deep Learning project, and we needed a deep-learning model for complex pattern recognition with enough documentation for our internal team to take over confidently. We appreciated the discipline around reproducibility, network architecture, training stability, regularization, and GPU efficiency. The team kept technical detail available when we needed it, while still making review sessions understandable for business stakeholders. Most importantly, we ended up with higher-quality predictions on difficult cases without sacrificing a disciplined evaluation process. The team packaged reproducible training notebooks, checkpoints, metrics, and tuning documentation in a way that made the next stage straightforward.

A
Ananya Rao
🇮🇳 India
Deep Learning
4.7 / 5   •   4 months ago

We asked the team to revisit our Deep Learning process and produce a deep-learning model for complex pattern recognition; their approach was structured from discovery through final validation. They kept a close eye on training stability, regularization, GPU efficiency, validation strategy, and reproducibility. Progress updates were concise, and the evidence behind important decisions was easy for us to verify. The final result gave us higher-quality predictions on difficult cases without sacrificing a disciplined evaluation process. We received reproducible training notebooks, checkpoints, metrics, and tuning documentation, and the transition into day-to-day use was smooth.

C
Chloé Dubois
🇫🇷 France
Deep Learning
5 / 5   •   5 months ago

Our previous approach to Deep Learning was producing inconsistent results, so we asked the team to build a deep-learning model for complex pattern recognition with stronger controls. A lot of value came from the attention to GPU efficiency, validation strategy, reproducibility, network architecture, and training stability. Instead of hiding uncertainty, the team documented it and showed us where additional data or different assumptions would change the result. Most importantly, we ended up with higher-quality predictions on difficult cases without sacrificing a disciplined evaluation process. The team packaged reproducible training notebooks, checkpoints, metrics, and tuning documentation in a way that made the next stage straightforward.

Request an NLP Project Quote

Tell us what text you need to process, the output you expect, your data volume, language and integration context. Rudrriv will review the requirement and recommend the most suitable package or custom scope.

Business objectiveExplain what decision, workflow or product feature the NLP output needs to support.
Text data & volumeShare a representative sample, file format, approximate record count and whether the text is already cleaned.
Labels & expected outputInclude your category taxonomy, entity types, target fields, examples of correct outputs or existing annotations.
Language & domainTell us the language or languages and whether the text contains technical, legal, financial, medical or other specialist terminology.
Current stack & integrationShare existing Python code, APIs, cloud services, application constraints or the environment where the output will be used.
Deadline & constraintsInclude your target date, performance priorities, privacy constraints and any third-party-service restrictions.
Helpful to include: sample text, labels or taxonomy, language, data volume, expected output, current baseline, integration target, deadline and preferred package. Do not send sensitive information you are not authorized to share.
NLP SERVICE ENQUIRY

Request an NLP Scope Assessment

Share your contact details and project requirements below. Your enquiry will be sent directly to support@rudrriv.com for review.

Please include enough detail for Rudrriv to assess the technical scope and delivery path. Your information is used to respond to this enquiry.